Pulling a Production WordPress Database Into Development: Two Ways It Fails Without Telling You
Pulling the production database into development sounds like the most routine job in WordPress work: export, download, import, done. We run it several times a week. On one day in August our own pull reported success twice while doing something else. The first time it left 1,527 posts still pointing at the live site. The second time, the “backup” it made of the development database before overwriting it was 170 bytes of nothing. Neither failure printed an error.
Quick Summary: A correct pull has six steps: export on the server, download, delete the server copy, back up the development database, import, and run a URL search-replace. The two steps that fail silently are the last two. The search-replace can rewrite a URL into itself and still report “changed”, and a wp db export | gzip pipeline hides a failed export behind gzip’s exit code. After every pull, count the production URLs left in the database and check the backup’s size. On Trellis, wp-ops database-pull does all six steps and handles both cases.
What a pull has to do
Whatever tool runs it, a database pull from production into a Trellis development site comes down to the same sequence:
- Export on the server.
wp db export - | gzip > dump.sql.gzin the site’s directory, so the dump never touches/tmpand travels compressed. - Download it into the development site’s directory.
- Delete the dump from the server. A forgotten
.sql.gzin a web directory holds every customer email and password hash on the site. - Back up the development database before you overwrite it. Development often holds work that never reached production: a page being built, test orders, settings you were trying out.
- Import the dump.
- Replace the production URL with the development one, with
wp search-replaceacross all tables.
Steps one, two, three and five fail loudly. A broken SSH connection or a full disk stops the run with an error. Steps four and six are where a pull can look finished and not be.
Failure one: a search-replace that replaces nothing
WordPress stores absolute URLs everywhere: in post content, in image blocks, in menu items, in options, in serialized widget settings. After an import, every one of them still says https://example.com. The search-replace rewrites them to http://example.test, and if it doesn’t happen, the development site looks fine while quietly using the live one. Images load from production, so a missing upload in development goes unnoticed. Links you click in development land you on the live site, where you might edit something without realising which tab you are in.
Our pull read the production hostname from the Trellis site configuration. The play also loaded the development wordpress_sites.yml, and in Ansible a file loaded that way outranks the environment’s own settings. So “the production hostname” resolved to the development hostname, and the command that ran was, in effect, “replace example.test with example.test“. WP-CLI did exactly that, and the task reported changed. On a real pull of imagewize.com, 1,527 posts still held the production URL afterwards.
The fix was to read each end’s hostname from its own environment’s file by name. The lesson is broader: don’t trust the exit status of a search-replace, count what is left. One query after the pull settles it:
trellis vm shell --workdir /srv/www/example.com/current -- \
  wp db query "SELECT COUNT(*) FROM wp_posts WHERE post_content LIKE '%//example.com%'" --path=web/wp
Anything above zero means the replace did not run against the right hostname. The same check in the other direction, looking for .test on production, is worth running after any push or migration. Block patterns that build image URLs from the theme directory write those URLs into the database, so they survive long after the pattern file has changed.
Failure two: a backup that is only a gzip header
The pre-import backup is the step you never look at, because you only need it on a bad day. Ours is the same pipeline as the export on the server: wp db export - | gzip > backup.sql.gz.
A shell pipeline reports the exit status of its last command. If wp db export fails, gzip still compresses the empty input it received, exits 0, and the pipeline succeeds. What you get is a valid gzip file of about 170 bytes containing nothing. The import then overwrites the development database, and the backup that was supposed to catch a mistake has nothing in it.
For us the export failed because the development site had moved into a virtual machine. trellis-cli’s trellis vm start runs development in a Lima VM, with WordPress and MariaDB inside it. The wp on the Mac can read the site’s .env file, but the database those credentials belong to is in the VM, so every development-side command failed with “Access denied for user”. The import and search-replace failed loudly. The backup failed silently, every time.
Two habits catch this. In any script of your own, start with set -o pipefail, so a pipeline fails when any command in it fails. And after a pull, look at the backup, from the site directory:
ls -lh database_backup/ | tail -3     # a real dump is megabytes, not bytes
gzip -t database_backup/example_com_development_*.sql.gz && echo ok
Our playbooks now detect a VM development site from .trellis/lima/inventory in the Trellis directory and run the development-side commands through trellis vm shell. The VM mounts the site directory at the same path, so the dump and the backup land where both sides can see them. After the change, the same pull produced a 13 MB backup and left 0 production URLs in wp_posts.
One command for the whole pull
We keep all of this in wp-ops, our open-source command line for Trellis sites, so nobody has to remember the six steps or the two checks. Run it from inside your Trellis project or its Bedrock site:
brew install imagewize/tap/wp-ops

wp-ops database-pull example.com production   # export, download, back up dev, import, search-replace
wp-ops files-pull example.com production      # rsync the uploads directory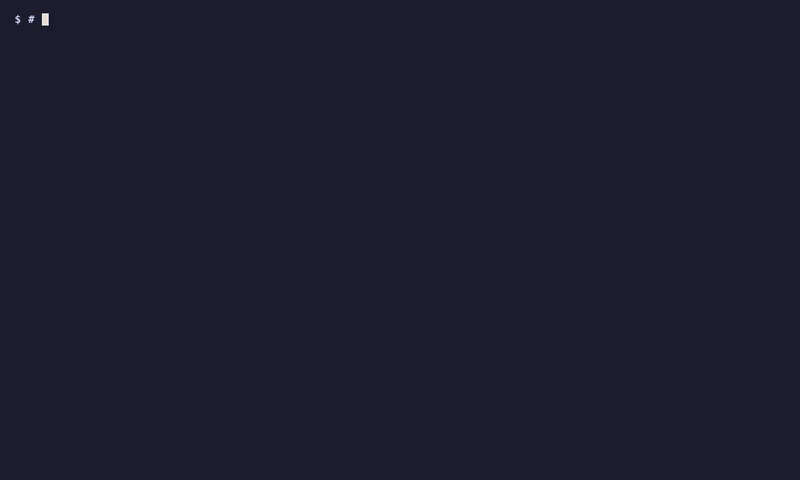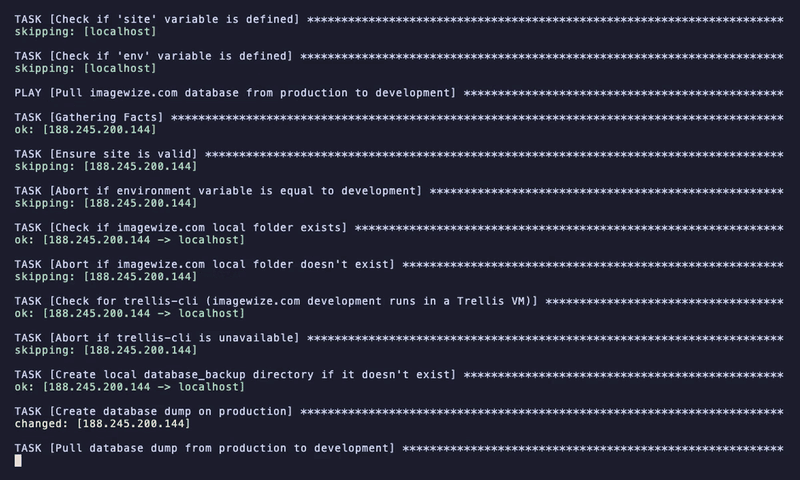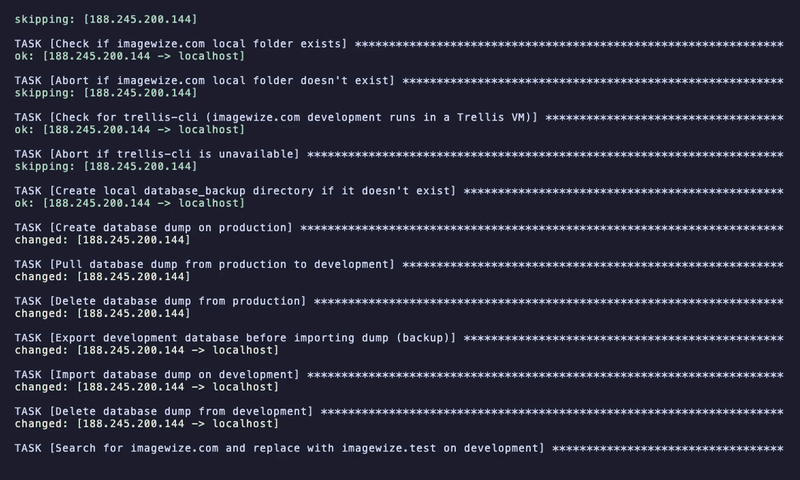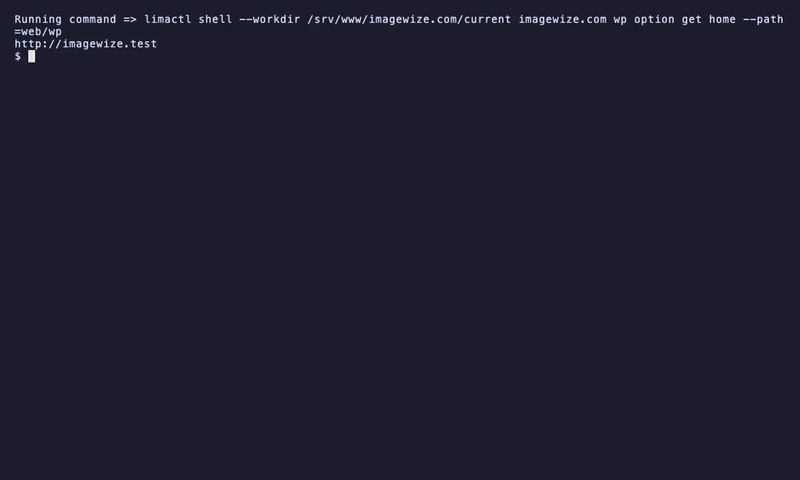
database-pull runs the Ansible playbook against your Trellis project, reads both hostnames from their own environment files, and works with a host-local or a VM development site. If you would rather not go through Ansible, wp-ops db-pull does the same over plain SSH and asks for confirmation before it overwrites anything. Every pull leaves a timestamped backup in database_backup/, so it is never a one-way trip. The backup guide covers pushing in the other direction, scheduled backups, and the playbooks on their own if you want to copy them into a Trellis project.
The same pull is also exposed to Claude and other AI assistants as an MCP tool, which our wp-ops introduction explains. For how we use a fresh copy of production while building themes, see our FSE theme workflow on Trellis and Bedrock.
Frequently asked questions
- Why search for //example.com instead of https://example.com? Starting at the two slashes matches http, https and protocol-relative URLs in one pass, so an old http link in a post from years ago is rewritten too.
- Is wp search-replace safe for serialized data? Yes. WP-CLI unserializes PHP-serialized values, replaces inside them and serializes them again with the correct string lengths. A raw SQL REPLACE on the same tables breaks serialized widget and theme settings whenever the old and new URLs differ in length.
- Do I also need to pull the uploads? The database only stores references to media files. Without the files, images in development either break or, if the search-replace failed, load from production. Pull the uploads directory separately, for example with wp-ops files-pull.
- Can I push my development database to production the same way? You can, and the push backs up the remote database first, but it overwrites everything that changed on production since your last pull: orders, comments, form entries, edits by other people. For content changes, publishing the individual pages is almost always the safer route.
- Does this work with the trellis-cli virtual machine? Yes. The playbooks detect a Lima VM development site from .trellis/lima/inventory and run the development-side commands inside the VM through trellis vm shell. A site that runs directly on your machine works without any change.
Want Backups and Environments Handled for You?
We offer managed WordPress hosting built on Trellis, with daily encrypted backups, updates tested on staging before they reach production, Nginx, Redis object cache, automated deployments via Ansible, and Bedrock structure on Hetzner EU. No shared hosting, no page builders, no surprises.
- Trellis + Bedrock on Hetzner EU (Frankfurt / Helsinki)
- Nginx + FastCGI caching + Redis object cache
- Automated deployments via Ansible, SSL via Let’s Encrypt
- From €49/month, or €65/hour for one-off server work